


Introduction
Smartphone owners demand instant responses every time they tap a glass display screen. Sluggish screens frustrate buyers and drive them away within seconds. Forward-thinking companies rely on Site Reliability Engineering to keep their digital services running smoothly day and night. Tech professionals shorten this practice to SRE in everyday office conversations. The field connects standard software coding directly with real-time operations tasks. Engineers craft software scripts that watch network traffic, prevent outages, and resolve critical errors. An education hub like SRESchool.com equips students and organizations with the right tools to master this field. The platform provides direct access to hands-on exercises and expert enterprise guidance.
What Is SRESchool.com?
Reliable tools perform their assigned duties without fail whenever someone switches them on. Consider your household refrigerator. Cool air fills the cabinet the second you pull the handle open. You lose expensive groceries if the motor stops humming. SRE empowers technology groups to maintain that same level of dependability across complex digital networks. Team members measure response times, log software bugs, and write automated repair routines. They study previous disruptions carefully to stop the same bug from recurring. Instead of relying on slow human fixes, engineers write software that repairs computers on its own.
Why Does SRESchool.com Matter?
Modern society depends on giant cloud networks, secure data vaults, and interconnected web applications. These technical components communicate continuously across delicate digital pathways. Because of this deep connection, a single bad script can cut off access for millions of eager users. Digital storefronts lose thousands of dollars whenever checkout pages freeze up. Banking portals trigger public alarm when customer balances fail to display. SRE helps engineers catch tiny glitches before external shoppers ever notice a slowdown. Businesses protect user trust because teams treat reliability as an everyday engineering priority.
What Does an SRESchool.com Team Do?
A dedicated reliability crew watches operational graphs on active dashboard monitors around the clock. They write automated rules that trigger alerts whenever a database uses up too much processor power. Techs jump into action immediately and restore broken links whenever a cloud server stalls. Staff members compose clean scripts that reboot stuck programs without human intervention. They project user growth months ahead so sudden traffic rushes do not overwhelm the system. Team members draft a detailed postmortem document after resolving any major service interruption. This report outlines the failure and outlines specific upgrades to protect the platform from future crashes.
Key SRE Terms Made Easy
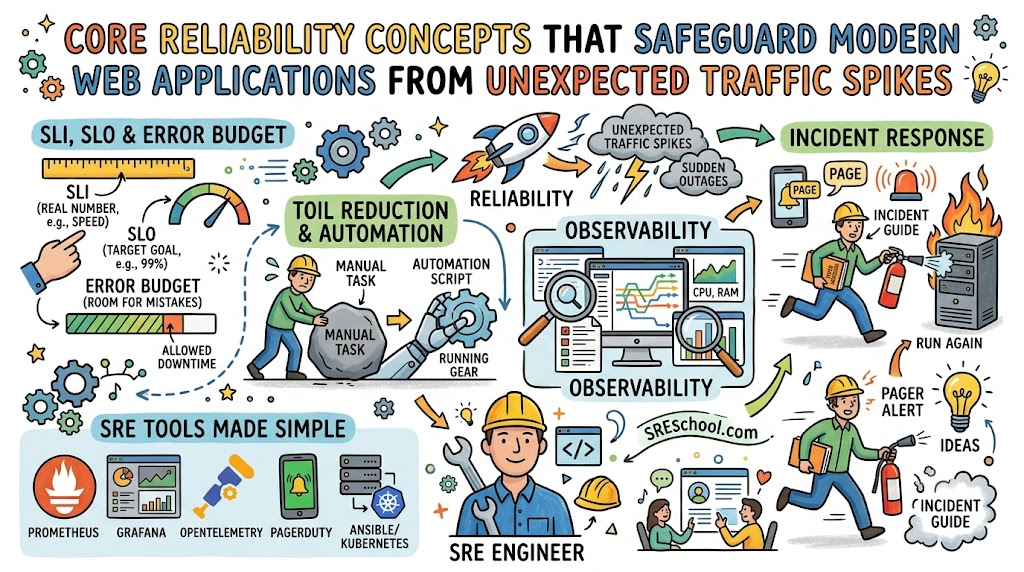
Engineers rely on special vocabulary to track service health and guide daily work. An SLI tracks a real system metric like data delivery speed. An SLO sets the target goal that the team promises to preserve for users. The error budget tells software makers how many minor glitches they can risk while launching updates. Toil describes boring, manual computer chores that workers should replace with automated scripts. Observability lets engineers view internal machine operations by analyzing logs, metrics, and network traces. On-call describes an engineer who carries an alarm receiver to fix urgent system issues at night.
| SRE Term | Simple Meaning | Example |
| SLI | A real measurement of service speed or uptime | A server delivers web pages in under half a second |
| SLO | The operational goal that a team promises to hit | The platform serves users fast ninety-nine percent of the time |
| Error Budget | Safe room for minor glitches or fresh updates | A business permits forty minutes of downtime per month |
| Toil | Boring manual steps that computers can execute | Deleting old cache folders by hand every morning |
| Observability | Digital clues that show internal computer health | Checking network logs to isolate a line break |
| Incident | An unplanned disruption that hurts app quality | An online checkout cart fails to accept credit cards |
What Is SRE Training?
New students build valuable technical skills through structured SRE Training programs. Instructors teach the core principles of cloud architecture, performance targets, and live system monitoring. Students construct code that frees up disk space before server drives fill completely. The curriculum trains people to resolve unexpected production emergencies with calm, steady teamwork. Learners discover how to eliminate wasteful toil by writing modern automation scripts. Hands-on labs provide deep practical exposure because reading textbooks alone cannot prepare you for live server panics. Learning centers like SRESchool.com guide students through practical exercises that build lasting technical skills.
What Is SRE Certification?
An official SRE Certification validates an engineer’s grasp of foundational operational safeguards. A Certified Site Reliability Engineer demonstrates strong competence across performance monitoring, incident response, and tracing tools. This formal assessment provides learners with a clear curriculum and impresses technical recruiters. Still, a paper credential cannot replace real hours spent fixing active infrastructure. Smart engineers combine exam study with real configuration experiments on live cloud providers. You gain genuine mastery when you deploy, break, and fix test networks with your own hands.
What Is a Site Reliability Engineering Course?
An effective Site Reliability Engineering Course walks you through technical principles in sensible steps. You begin with basic Linux commands, networking rules, and cloud server configurations. Next, you construct visual dashboards that highlight operational metrics. Then you learn how to balance uptime objectives with urgent incident handling. Afterwards, you compose scripts that automate mundane tasks and pressure-test cloud networks. Finally, you execute realistic emergency simulations to sharpen your problem-solving speed. This ordered path helps beginners and seasoned engineers advance their careers.
SRE Tools Made Simple
Modern reliability specialists run versatile applications to protect massive computer networks from disaster. Monitoring agents record processing speeds, while visualization tools map out data trends. Logging programs collect timestamped system histories so workers can inspect past actions. Tracing tools follow a single user click as it travels through complex server clusters. Alert platforms ring emergency alarms the moment server latency rises. Teams depend on popular engines like Prometheus to scrape numbers and Grafana to craft helpful dashboards. They implement OpenTelemetry so distinct systems talk to one another without friction.
| Learning Area | What Learners Can Practice |
| Metrics Collection | Collect machine health stats every ten seconds using Prometheus |
| System Dashboards | Build clear CPU utilization charts inside Grafana |
| Open Tracing | Trace database calls across remote servers with OpenTelemetry |
| Alert Management | Send emergency notifications directly to on-call mobile apps |
| Task Automation | Write Python scripts that clear stale records from full drives |
Real-Life Scenarios
- A retail website welcomes thousands of buyers during a morning launch, but autoscaling software launches extra servers to keep page speeds blazing fast.
- An enterprise storage disk reaches full capacity overnight, activating an automatic script that purges old backup archives before users notice any delay.
- A broken code release introduces payment bugs, but the team rolls back the deployment instantly because live charts flash red warnings.
- A hardware rack loses power in a data warehouse, but backup machines redirect all user traffic without dropping an active session.
What Is SRE Consulting?
Independent SRE Consulting brings seasoned professionals into organizations to review architecture and fix operational gaps. These advisors examine server landscapes, investigate past outages, and pinpoint weak links. They help leadership draft realistic uptime targets that protect user joy without halting code updates. Consultants also train internal personnel to coordinate smoothly during chaotic emergencies. Moreover, these experts instruct developers on how to script away boring manual chores. They hand over a practical improvement roadmap that safeguards business infrastructure for the long haul.
What Is SRE as a Service?
Young ventures often lack the budget to hire a full team of senior engineers. Flexible SRE as a Service allows organizations to hire external talent on an ongoing basis. These specialists oversee client servers, resolve infrastructure breakdowns, and manage urgent midnight alarms. They evaluate monthly error budgets and configure safe cloud architecture. Still, businesses must outline their core technical needs before hiring an external group. Clear communication between both sides secures dependable protection without the heavy overhead of internal hiring.
What Is Corporate SRE Training?
Targeted Corporate SRE Training aligns entire software departments around identical operational strategies. Experienced trainers craft custom lessons that mirror the actual toolchains and cloud platforms of the company. Programmers and operations personnel adopt shared vocabulary regarding service uptime and software releases. They rehearse simulated disaster drills together so no individual loses composure during live outages. Teams learn to balance on-call duties fairly while removing repetitive manual tasks. Focused workshops instill productive habits that keep enterprise platforms running fast and secure.
Common Mistakes to Avoid When Choosing SRE Paths
- Teams frequently establish extreme hundred percent uptime targets that stop developers from launching helpful features.
- Businesses purchase costly visualization platforms without teaching their staff how to interpret the charts.
- Managers issue alarms for minor hiccups, driving workers to ignore critical alerts because of warning fatigue.
- Executives rename traditional operations teams without granting workers the time to write automation software.
- Developers skip post-incident reviews, which practically ensures that identical errors will cause future disruptions.
- Organizations view reliability as a side chore instead of embedding it into early product design.
- Technicians automate fragile, manual procedures rather than redesigning the broken architecture underneath.
- Companies force engineers to chase theoretical certificates while withholding access to hands-on testing clouds.
How SRESchool.com Can Help
SRESchool.com operates as a comprehensive hub for modern reliability education and professional enterprise solutions. The platform delivers practical SRE Training designed to help beginners and working engineers master production environments. Candidates prepare thoroughly for an official SRE Certification using interactive labs and step-by-step guidance. Learners can enroll in a focused Site Reliability Engineering Course to understand error budgets, system observability, and incident remediation. Technicians expand their toolkit through an accessible SRE Tutorial library covering essential SRE Tools like Prometheus and Grafana. Furthermore, the organization provides expert SRE Consulting to fortify fragile cloud setups and Corporate SRE Training to align development teams. Expanding businesses can also access scalable SRE as a Service to secure continuous production support. Each service emphasizes hands-on engineering principles that keep modern software resilient and available.
Frequently Asked Questions
1. Which specific operational challenges does Site Reliability Engineering solve?
SRE prevents costly service outages by treating system administration as a software engineering task. Developers apply disciplined coding practices to handle server traffic, storage drives, and cloud connections. This approach replaces repetitive manual maintenance with robust automation routines. As a result, web applications remain stable and responsive for global users around the clock.
2. How does SRE differ from standard DevOps methods?
DevOps provides a broad cultural model that encourages developers and system operators to collaborate closely. SRE adds precise mathematical targets, specific engineering routines, and practical measurement tools to that shared mindset. You can view DevOps as the general goal and SRE as the exact operating manual.
3. Must aspiring reliability engineers learn to code first?
Basic programming knowledge proves vital for anyone seeking an engineering role in this field. You will write short software scripts in languages like Python or Go to automate server operations. You do not need to build complex web apps, but you must write programs that interact with operating systems.
4. Where do engineers draw the line between SLIs and SLOs?
An SLI measures the real performance of your system, such as average response time over an hour. An SLO defines the performance target that your team promises to maintain for customers. The SLI shows your current speed, while the SLO marks your promised standard.
5. Why do businesses use error budgets instead of chasing zero downtime?
Targeting complete perfection stalls product development and drains financial resources. Minor technical glitches occur naturally inside massive distributed networks. An error budget creates a safe zone for minor failures during new code deployments. This policy gives developers room to innovate without risking overall customer trust.
6. What primary software tools should a beginner explore first?
Begin your journey by practicing basic Linux terminal commands, simple Python automation, and Git version control. Next, explore container technologies like Docker to package software reliably. After mastering these basics, build live observability dashboards using Prometheus and Grafana. These tools show you what happens inside active servers.
7. How many months does it take to learn core SRE practices?
A committed student can grasp foundational reliability principles within three to six months of regular study. Having previous experience with computer networks or system administration speeds up your progress. Success comes from running experiments in live cloud environments rather than reading static books.
8. What happens during an emergency on-call shift?
An on-call engineer carries an active notification device and stays prepared to handle urgent server alerts. When a live service drops offline, the monitoring tool sounds an immediate alarm. The responder opens their laptop, isolates the root failure, applies a fix, and restores normal traffic quickly.
9. Do non-technology companies gain real value from Site Reliability Engineering?
Every organization that relies on internal software, digital shopping portals, or mobile apps benefits from SRE. Hospitals, logistics providers, banks, and retail outlets rely on computers every single hour. SRE methods prevent costly server outages across modern commercial sectors every day.
10. Why do engineering leaders actively fight against operational toil?
Toil describes repetitive, manual computer chores that generate zero enduring value for an expanding business. Manually clearing log directories or resetting user passwords represents classic toil. This dull work exhausts skilled engineers and wastes hours that they could spend building automated tools.
11. How does outside SRE Consulting upgrade an existing IT department?
SRE Consulting brings veteran reliability architects into your workplace to spot architectural weaknesses and upgrade daily workflows. These advisors train internal staff to set reasonable targets and handle serious outages with calm teamwork. Outside mentors help your department establish healthy habits far faster.
12. Can a technical certification take the place of real troubleshooting experience?
A certificate demonstrates that you studied the material and passed a demanding technical test. Hiring managers still look for hands-on troubleshooting talent above all else. You should combine formal study credentials with personal cloud projects to demonstrate that you can manage real production environments.
CONCLUSION
Modern digital businesses rely on Site Reliability Engineering to maintain stable, responsive software for customers across the globe. This approach blends creative software coding with disciplined operational workflows to track health metrics, prevent costly downtime, and automate mundane computer chores. Anyone can enter this technical profession by studying clear tutorials, running labs in real cloud networks, and obtaining recognized credentials. Maturing organizations can partner with seasoned consultants and managed reliability providers to shield their systems from unexpected outages. Platforms like SRESchool.com equip curious learners and progressive companies with the exact training, courses, and enterprise guidance required to achieve modern software reliability.

Leave a Reply
You must be logged in to post a comment.