


Introduction
Modern commerce runs on pristine facts to steer critical investments every morning. Flawed records deceive managers, burn operating capital, and stall freight trucks across major transport corridors. Corrupted figures also scramble inventory counts and panic cashier staff. Cloud servers trade gigabytes of raw logs every second, so developers assemble sturdy digital paths for incoming transactions. This dynamic overview details pipeline movements, defensive checks, proactive warning networks, and collaborative habits that keep technical architectures humming smoothly. Observers will discover hands-on routines, error isolation tactics, and practical habits that protect enterprise databases. Educational portals like TheDataOps.org also publish clear, practical lessons for specialists seeking higher operational proficiency. Simple techniques quickly turn tangled spreadsheets into reliable tools for every office.
What Is DataOps?
DataOps gathers engineers, analysts, and operators into a cohesive, fast-moving workflow unit. Consider a community reservoir pumping fresh spring water through subterranean tunnels directly into kitchen sinks. The liquid flows through filtration grates, enters pressurized metal conduits, and pours into drinking mugs. Digital records travel through algorithmic channels following that exact path. A split conduit dumps mud into the flow, making the water completely undrinkable. DataOps combines talented practitioners, disciplined habits, and automated helpers to maintain crystal-clear digital conduits. Programmed tests examine every record before managers print early revenue recaps. Database administrators and business researchers stop pointing fingers over broken numbers and fix problems together.
Why Does DataOps Matter?
Ambitious organizations rely on crisp, punctual figures to delight daily shoppers. Lacking dependable protocols, business units suffer sluggish deliveries, blank columns, and distorted sums. Staff members squander sunny afternoons copying numbers across spreadsheet tabs manually. These manual handoffs fail constantly, so vital software pathways snap without warning. Chief officers study stale spreadsheets and place high-stakes corporate bets on pure guesswork. Frustrated departments trade blame whenever systems grind to a halt. DataOps removes miserable human drudgery by assigning repetitive steps to tireless scripts. Programmed scripts catch nasty glitches long before customers view their shopping carts.
What Is TheDataOps.org
TheDataOps.org serves as a friendly learning hub for modern engineering practices. The platform publishes clear articles on continuous delivery, pipeline design, automated checks, and system safety. Beginners read these lessons to build steady database pipelines that run smoothly every day. Visitors discover unbiased reviews of popular software tools, team frameworks, and workplace workflows. The site helps developers pick up actionable habits that deliver instant workplace value. Simple lessons show developers how to move raw records into live dashboards without leaks.
DataOps Training and DataOps Course
A focused DataOps Training initiative shows technical staff how to route figures smoothly. Participants master real data pipelines, Agile collaboration rhythms, and core DevOps fundamentals. They implement CI/CD routines, which build and test code changes automatically every afternoon. A well-rounded DataOps Course guides participants through automated testing across modern cloud setups. Practical screen time matters immensely because reading textbooks will never build operational confidence. When learners build real projects, they gain the skills to fix production crashes. Learning hubs such as TheDataOps.org supply clear learning tracks that build testing and monitoring skills step by step.
Comparison Table
| DataOps Area | Main Goal | Example Activity |
| Data Pipeline | Move data | Load daily sales data |
| Automation | Reduce manual work | Run jobs automatically |
| Testing | Find errors | Check missing values |
| Observability | Watch systems | Track failed jobs |
| Data Quality | Improve data | Check data rules |
| Orchestration | Manage steps | Run jobs in order |
DataOps Certification
A DataOps Certification confirms your solid grasp of resilient pipeline engineering. The credential demonstrates to managers that you know how to build clean, automated data conduits. Yet a paper certificate never replaces keyboard time or direct project problem-solving. True masters combine exam study with personal portfolio builds and active testing practice. Learners should start by practicing basic SQL syntax, Python logic, and cloud storage basics. Next, write automated validation scripts and run delivery routines inside shared repositories. Finally, pass the formal exam to validate your skills and advance your career.
Data Pipeline Automation
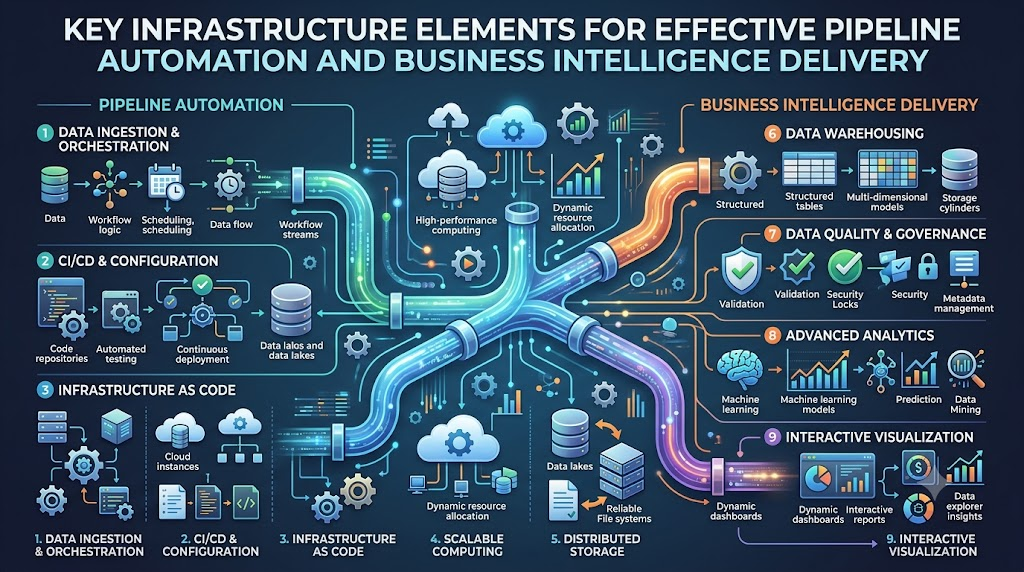
Data Pipeline Automation transfers records between systems without human intervention. Old offices relied on tired clerks who typed entries into spreadsheets late at night. Modern automated systems follow a six-stage path: Collect, Clean, Test, Process, Store, and Monitor. First, servers collect raw entries from store checkouts and mobile apps. Next, scripts strip out formatting garbage and test for blank spaces. Then, cloud engines calculate totals, save final rows into data warehouses, and monitor for delays. For instance, an automated supermarket system adjusts shelf numbers the instant a cashier scans cereal.
DataOps Tools
Tech groups rely on diverse DataOps Tools to simplify complex pipeline duties. Programmers write Python scripts to reshape disorderly tables into clean formats. Apache Airflow triggers jobs in a precise sequence so steps run without confusion. Apache Kafka gathers live activity streams, like website button clicks, and delivers them instantly. Apache Spark chews through massive database tables across linked server clusters. Hadoop holds huge file collections, while Kubernetes coordinates containerized software on remote cloud instances. Jenkins triggers test suites automatically every time an engineer saves new code. Grafana presents live system vitals on visual screens, while Tableau renders understandable visual charts. Smart teams pick tools that address real business bottlenecks.
DataOps Platform
A centralized DataOps Platform gathers isolated pipeline jobs into a unified command dashboard. The software directs data ingestion, file transformation, code testing, workflow scheduling, alert monitoring, and data access. Engineers oversee the entire data path through a single pane of glass. This visibility helps enterprises enforce security rules and protect sensitive customer records. Before picking a platform, directors must check licensing fees, security controls, and growth ceilings. Leaders must also ensure that the software links cleanly with their current tools.
Data Observability
Data Observability tracks pipeline vitals continuously so teams detect errors before users spot bad numbers. Technicians observe pipeline speeds, update frequencies, missing rows, and stalled tasks. They watch file sizes to spot sudden, unusual dips or spikes. For example, if a banking portal expects thousands of deposits but sees zero, an alert rings. Observability platforms dispatch immediate notices to engineers through messaging channels. These warnings help developers fix severed pipelines before executives start their morning meetings.
Data Quality Management
Data Quality Management keeps business numbers accurate, dependable, and clear. Neglected databases gather empty rows, duplicate accounts, weird spellings, and illogical values. For instance, a phone number with twenty digits breaches standard database rules right away. Automated quality rules run through incoming rows to stop invalid entries at the gate. Clean databases allow corporate leaders to make smart plans with complete confidence. Careful quality routines convert messy spreadsheets into reliable business facts.
DataOps Consulting
Firms that battle broken pipelines often hire professional DataOps Consulting teams. Experienced advisors examine messy architectures, slow manual workflows, mismatched tools, and missing automated checks. They pinpoint process bottlenecks and teach internal staff how to run smooth pipelines. Good consultants solve concrete technical issues rather than selling empty buzzwords. Helpful advisors leave client teams with faster workflows, reliable tests, and practical operational guides.
Real-Life Scenarios / Experiences
- An e-commerce platform spent four hours repairing broken customer logs each dawn, but automated Python scripts slashed that chore to two minutes.
- A regional health network dispatched clinic reminders with missing names due to blank database rows, but automated testing trapped the faulty files beforehand.
- A currency exchange exchange dropped six hours of market ticks when a node failed, but live observability alerts spurred engineers to restart workers immediately.
- A nationwide courier tracked divergent delivery tallies across regional depots, so technicians unified their pipelines into a single trustworthy truth hub.
DataOps Engineer Career Path
A DataOps Engineer connects raw databases to clean analytical reports. To begin, build your foundation with Python programming, SQL syntax, and basic Linux commands. Next, practice version control using Git, containerize tasks with Docker, and explore cloud environments. Study how Apache Airflow schedules tasks and write scripts that test raw files automatically. Create personal portfolio projects, like a routine that pulls and cleans public bus schedules. Publish your project files on public repositories so hiring managers can view your practical talent.
Common Mistakes to Avoid When Choosing Data Operations Strategies
- Procuring shiny software suites prior to untangling broken workflows: New licenses never mend chaotic workplace routines, so streamline human steps first.
- Bypassing automated test suites to hit an artificial launch date: Teams skipping validations spend their weekends troubleshooting catastrophic pipeline failures manually.
- Permitting dirty records to enter raw staging tables: Dirty records corrupt analytical models and make downstream company dashboards useless.
- Failing to train business users on updated platforms: Workers will return to dangerous personal spreadsheets if they do not understand modern tools.
- Restricting pipeline access to a single technical team: Secretive systems prevent junior engineers from fixing minor bugs during emergencies.
- Ignoring real-time notification setups: Silent pipeline errors hide inside databases for weeks if engineers forget to activate alert bots.
- Attempting total system automation on day one: Rushing complex overhauls causes burnout, so automate the easiest, most painful chore first.
- Abandoning clear system documentation: Future teammates will struggle to maintain pipelines safely if builders skip writing simple operational instructions.
How TheDataOps.org Can Help
Building modern data skills feels challenging, but TheDataOps.org makes the learning process clear. The platform shares plain guides on automation, pipeline health, testing frameworks, and popular tools. Whether you want to pass an exam or build faster pipelines, its guides turn complex engineering ideas into simple steps. The site shows professionals how data quality and system tracking protect enterprise records. By exploring these resources, engineers build the confidence to run dependable pipelines every day.
Useful DataOps Tools
| Tool | Main Use | Simple Example |
| Python | Data coding | Clean data |
| Airflow | Job scheduling | Run pipelines |
| Kafka | Data streaming | Move live events |
| Spark | Data processing | Process large data |
| Jenkins | Automation | Run tests |
| Grafana | Monitoring | Watch system health |
Frequently Asked Questions
1. What does a DataOps Engineer do every day?
Technicians in this role construct and protect automated conduits that ferry enterprise records securely across clouds. They write custom scripts to ingest disparate streams, prune bad characters, and feed warehouses. They also construct test batteries and inspect server clusters to patch hiccups before coworkers spot problems.
2. Can beginners learn DataOps without previous coding experience?
Eager newcomers can grasp these fundamentals quickly, though baseline programming experience speeds up real progress. Drafting short Python scripts alongside standard SQL filters forms an ideal foundation. Once you comprehend table relationships, you effortlessly grasp scheduling tools, diagnostic monitors, and deployment pipelines.
3. How does DataOps differ from traditional DevOps practices?
DevOps champions rapid delivery and automated testing for customer-facing software apps. DataOps borrows those very mechanisms and unleashes them upon volatile information pipelines. While application developers track program crashes, pipeline specialists guard both execution speed and information purity.
4. Why is data pipeline automation necessary for small businesses?
Lean startups lack the excess manpower required to clean messy records by hand. Offloading standard file handoffs to cron jobs lets employees focus on marketing, sales, and customer care. Automated pathways also dodge typo bugs, preserving crisp ledgers and true warehouse counts.
5. What is the fastest way to improve bad data quality?
Installing automated test barriers at the intake valve fixes dirty data instantly. Validate incoming files against negative currency numbers, absent names, and corrupted date formats. Catching tainted rows at the door stops errors from spreading across executive summaries.
6. What core tools should an engineer learn first?
Aspiring engineers must master basic SQL commands to query databases and Python to automate file transforms. Once you feel comfortable with scripting, learn Git branches to track modifications cleanly. Next, schedule basic workflows inside Apache Airflow prior to handling massive streaming software.
7. Does a DataOps certification guarantee a tech job?
Credentials signal academic dedication to recruiters, but they never surpass direct portfolio demonstrations. Hiring directors reward candidates who untangle real pipeline failures and share functional GitHub code. Supplementing course certificates with live database demonstrations paves a reliable road into industry positions.
8. How does data observability stop business report errors?
Continuous observability platforms track pipeline performance like automated security cameras. They register line volumes, latency numbers, and execution timestamps across each table. When an incoming file drops ninety percent of its normal size, alarms ping staff before leaders read bad reports.
9. When should a company hire DataOps consulting help?
Enterprises should summon outside advisors when unrelenting database outages overwhelm internal programmers. Veteran consultants scrutinize fragile systems, expose manual bottlenecks, and introduce rock-solid testing workflows. This guidance instills reliable habits into internal developers while rebuilding faulty data architecture.
10. What is continuous integration and continuous delivery in DataOps?
Continuous integration fires automated test suites whenever an engineer updates shared scripts. Continuous delivery carries those approved code adjustments directly into live production clusters without manual delays. Paired together, these principles allow teams to deploy pipeline enhancements multiple times weekly without interruption.
11. How does clean data improve company decision making?
Pristine facts empower corporate directors to chart strategic courses on concrete evidence instead of hunches. Marketing teams isolate effective campaigns, and inventory managers schedule restocking dates accurately. Verifiable facts prevent wasteful expenditures and assist organizations in serving customers brilliantly.
12. Why do data pipelines fail unexpectedly during normal runs?
Upstream partners often modify schema formats without notifying engineering squads beforehand. An external vendor renames an export column, or a remote server pushes blank rows. Automated tests detect these silent schema mutations immediately, sheltering downstream presentation tables from unexpected breakdowns.
Conclusion
Enterprises must handle information briskly to steer smart investments. When engineering departments deploy automated conduits, continuous quality rules, and dynamic observability, systems hum reliably. Mastering versatile languages and establishing validation barriers enables any practitioner to defend company intelligence. Instructive destinations like TheDataOps.org deliver structured lessons for workers keen to enhance their architecture proficiency. Automate your most irritating daily chore today, and keep perfecting your pipeline craftsmanship.

Leave a Reply
You must be logged in to post a comment.